A chatbot based on your documents is useful when it searches the right sources, identifies its evidence and does not invent answers when uncertain. This requires organised knowledge, access controls, traceable sources and a clear handoff point.
We explain knowledge preparation, the relationship between retrieval and answers, access boundaries and tests to verify behaviour before launch.
How does a knowledge-base chatbot work?
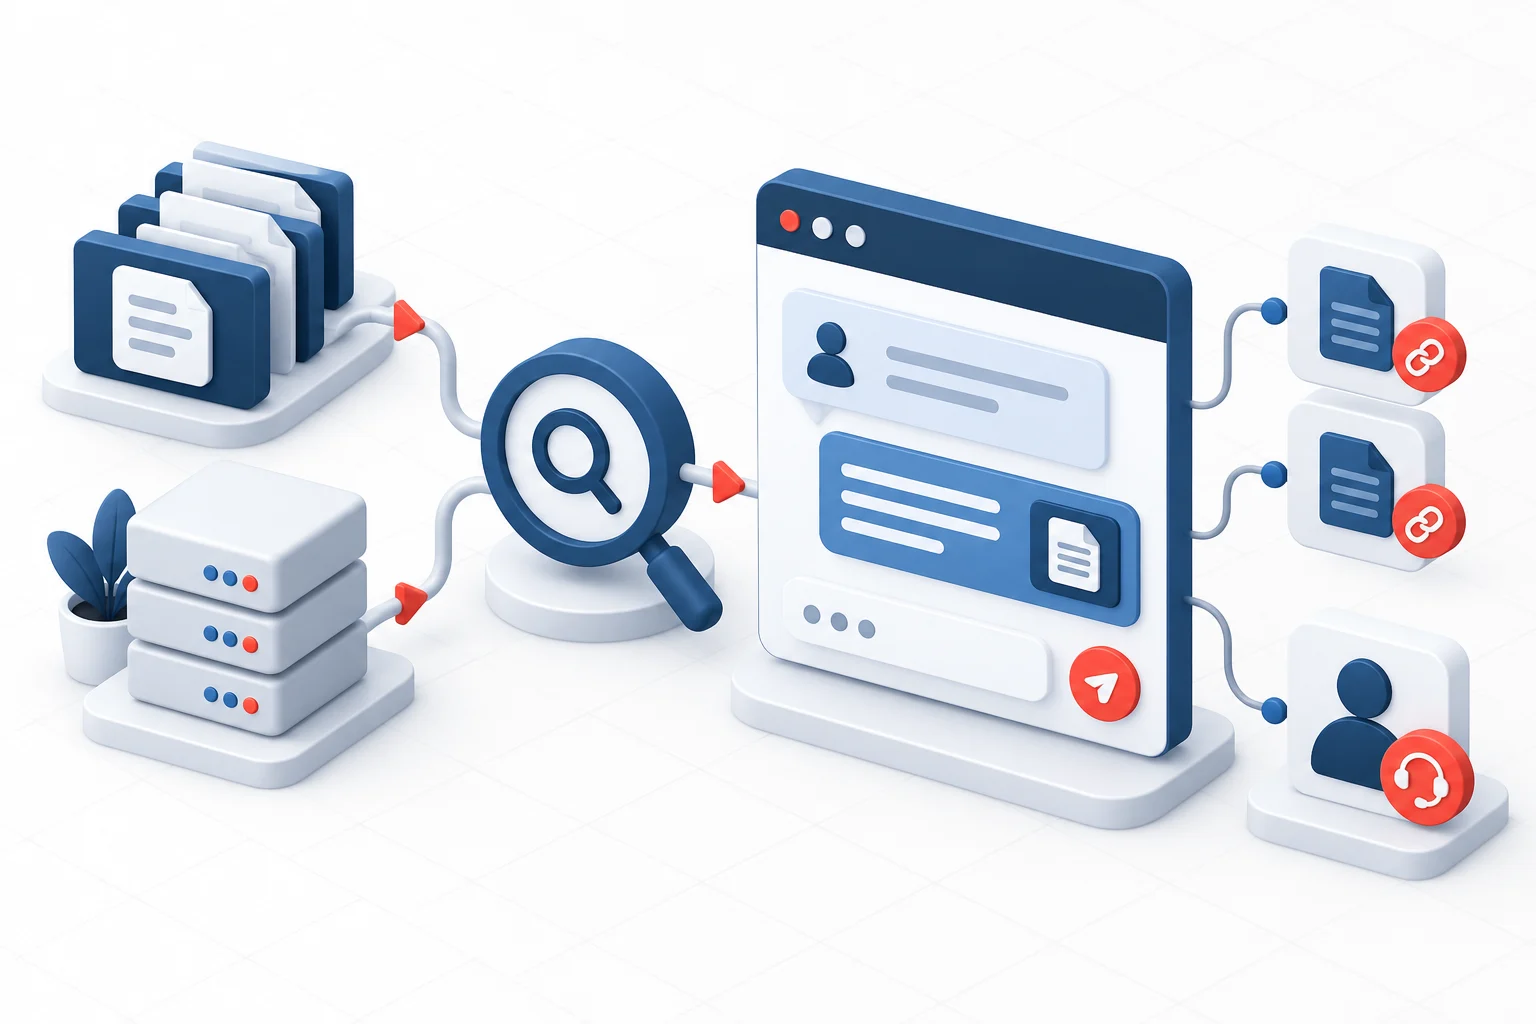
The system first retrieves source passages relevant to the question, then uses them to draft an answer. This can improve relevance but does not, by itself, guarantee correctness or enforcement of access permissions.
 Open image full size
1. Make your knowledge searchable
- Remove or flag outdated and conflicting documents.
- Give every document a title, owner, validity period and access level.
- Split long documents into logical chunks that remain meaningful on their own.
- Check information in tables, attachments and images separately; not every processor preserves their structure well.
2. Enforce access permissions during retrieval too
- After identifying the user, determine which sources they are allowed to access.
- The retrieval layer must select documents only from this authorised scope.
- Show the source actually used alongside the answer where the interface and permissions allow it.
- Do not unnecessarily log complete questions, document passages or sensitive answer content.
3. Plan for uncertain answers
| Helyzet | Correct behaviour |
|---|---|
| No suitable source | State that no answer was found in the knowledge base. |
| The sources conflict | Highlight the discrepancy and request human review. |
| A personal matter needs handling | Hand off to an identified support channel. |
| An action is requested | Run only after separate permission and parameter checks, with approval where needed. |
4. Account for direct and indirect prompt injection
- Treat user questions, uploaded files, webpages and text from external systems as untrusted data.
- Validate model-proposed tool calls in code against the user's permissions and original request.
- Retrieved content must not gain access to secrets, internal instructions or another user's data.
- Require explicit human approval for high-risk or irreversible actions.
5. Test with a question set, not a demo
- Prepare common, rare, ambiguous and intentionally invalid questions.
- Check answer claims, sources, access boundaries and appropriate refusals.
- Measure the human handoff rate and the time needed to correct a wrong answer.
- Rerun key tests after document updates, because knowledge changes also affect retrieval results.