An API integration involves more than connecting two endpoints. Define data ownership, authentication, field meanings, error handling and what happens during partial outages or repeated requests.
This guide orders the key design decisions: process mapping, data mapping, permissions, idempotency, retries, logging and a controlled rollout.
1. Map the data flow
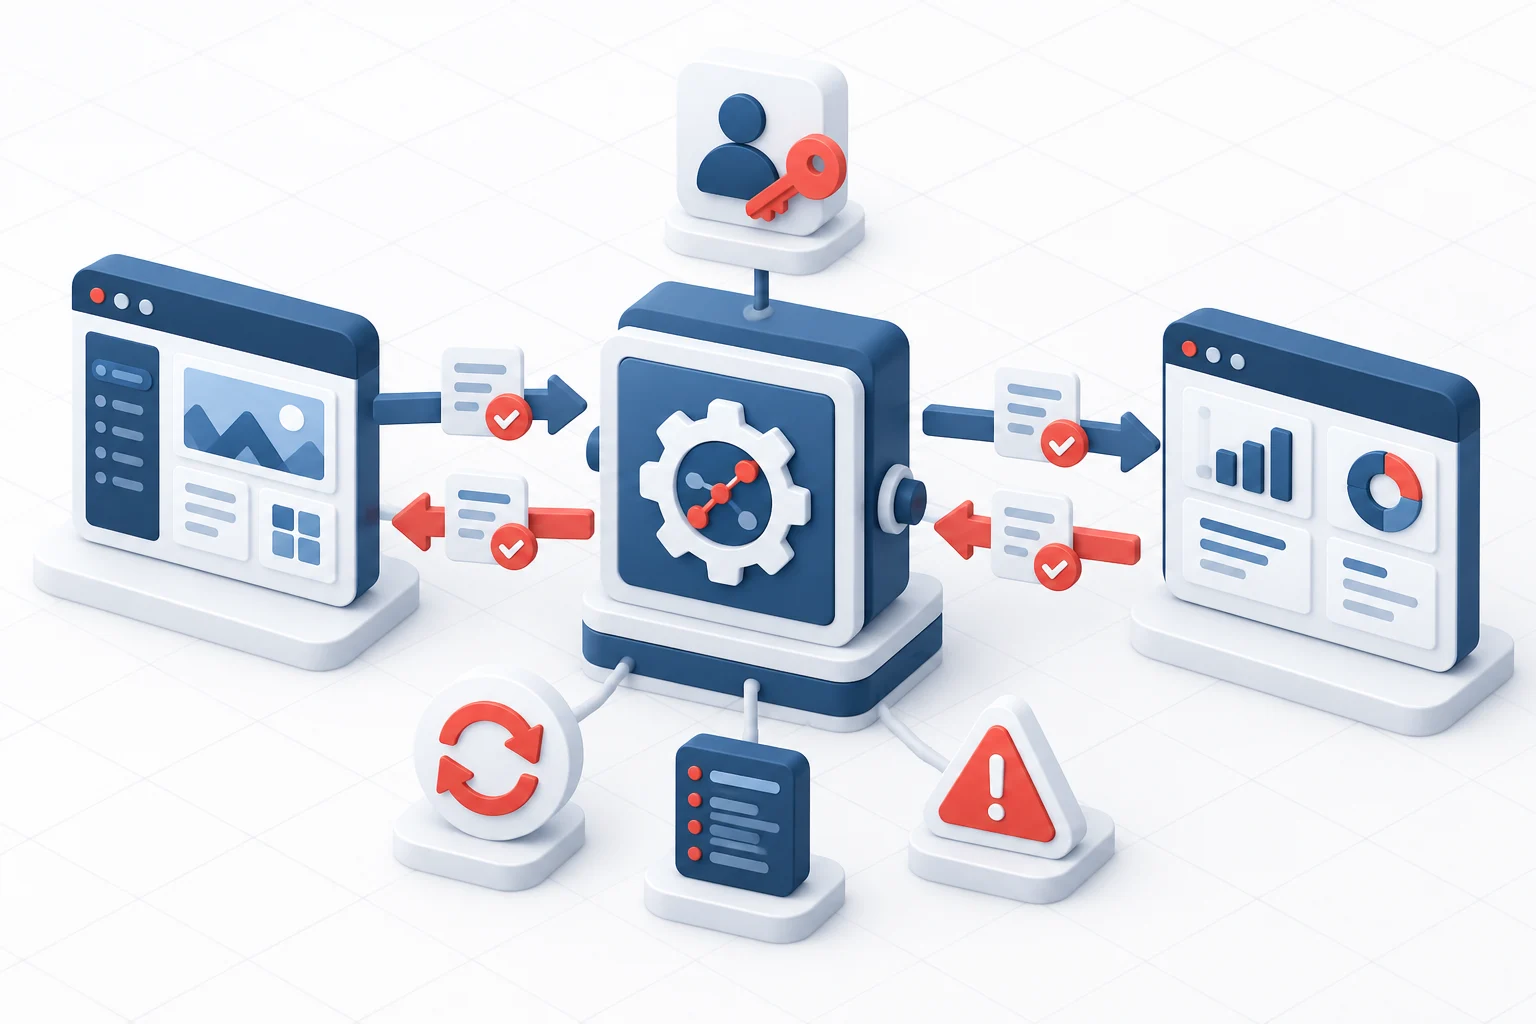
Identify each data item's system of record, what triggers transfer and where the result appears. Include error responses, delayed responses and missing responses in the process map.
 Open image full size
2. Map fields and states
| Question | Example |
|---|---|
| What is the unique identifier? | The external order ID, not the displayed sequence number. |
| Which fields are required? | Currency, amount and customer ID are all required. |
| Which system is allowed to write it? | Only the billing system updates billing status. |
| How do we delete data? | Soft deletion, revocation or permanent removal. |
| What happens with unknown values? | Reject, use a default or send to a manual processing queue. |
3. Restrict access
- Use a dedicated integration account or key, not an employee's personal access.
- Allow only the required operations and data scope.
- Store the secret in secure configuration, not source code or logs.
- Document key rotation and provide a way to revoke access quickly.
- Verify incoming webhook signatures and timestamps where supported by the provider.
4. Plan for retries and partial failures
- Identify operations that could create duplicates when a request is repeated.
- Use an idempotency key or external ID where the receiving API supports it.
- Retry only transient failures, using increasing delays and an upper limit.
- Send persistently failing items to an inspectable error queue rather than silently losing them.
- Logs should include a correlation ID, status and timestamp, but no authentication secrets.
5. Roll out reversibly
- A test environment and documented test scenarios.
- A pilot starting with limited data or a restricted user group.
- Compare record counts between source and destination systems.
- Alerts for error rates, queue backlogs and unusual traffic.
- A stop switch and manual processing procedure for outages.